Fractile raises $700M in funding, aiming to accelerate AI inference by 100x
Fractile raises $700M in funding, aiming to accelerate AI inference by 100x

2026-11-13 22:06
Introduction: Shifting from SRAM to 3D-stacked DRAM to address memory bandwidth bottlenecks. AI inference computing is increasingly recognized as the most critical computational demand for AI in the coming years.
AI inference computing will become the paramount computational requirement for AI in the coming years, and this has gradually become a consensus.
Inference computing can be decomposed into two key dimensions: cost and latency.
The benefits of accelerating inference speed are becoming especially prominent in an era where AI is increasingly agent-driven.
Specifically, under the same cost constraints, faster inference enables high-latency, high-compute-intensity agent tasks to complete within shorter timeframes, thereby enhancing overall system efficiency.
Fractile is a full-stack AI inference company dedicated to building foundational inference technologies from scratch, breaking through the Pareto frontier limitations between "cost and latency" in inference computation.
Its initial goal is to achieve 100x faster AI inference speeds compared to existing hardware while reducing costs to one-tenth.
Recently, media reports indicate that Fractile has closed a new round of financing worth approximately $700 million, led by Lightspeed and Redpoint, with participation from Thrive Capital, raising its valuation from $1 billion to $6.5 billion.
In May 2026, it secured a $220 million Series B round co-led by Accel, Factorial Funds, and Founders Fund, with additional participation from Conviction, Gigascale, O1A, Felicis, Buckley Ventures, and 8VC.
Earlier, Intel’s former CEO Pat Gelsinger also invested in the company.
Additionally, according to Bloomberg, Anthropic has placed an initial chip order with Fractile valued at $250 million.
When Agent execution stalls at memory bandwidth, Fractile bets on in-memory computing
Modern advanced AI systems exhibit a defining characteristic: the scale of compute deployed during inference correlates positively with model performance.
The emergence of the Agent era, combined with this trait, enables many scientific and mathematical derivations and breakthroughs to be completed—either assisted by or independently executed by AI.
These high-value tasks often require consuming tens of millions, even hundreds of millions of tokens. However, current top-tier models, constrained by massive model sizes and insufficient inference compute resources, typically achieve inference speeds of only 30–40 tokens/s. Completing such long-form tasks may take weeks, and including iterative feedback and tuning extends the timeline significantly.
Thus, the time from input instruction to output generation has become the critical bottleneck limiting cutting-edge model capabilities. From an industrial perspective, inference computing serves both as the revenue engine of the AI sector and the primary constraint on its scalable expansion.
In the AI inference technology stack, the entire computation process is heavily constrained by memory performance, particularly memory bandwidth. Breaking this limit could accelerate generation speeds from 30–40 tokens/s to 1,200 tokens/s, compressing work previously taking a month into just one day.
AI inference hardware companies generally face two technical pathways. The first is specialization—focusing on highly specific workloads and designing chips tailored precisely to these niche demands. However, AI model architectures evolve rapidly, while chip design, validation, tape-out, manufacturing, and testing require extensive timelines, making this path inherently uncertain.
The second approach involves fundamentally redefining how computational operations are executed—redesigning chip architecture using novel underlying modules and building scalable systems based on this foundation.
Fractile has chosen this path. Its R&D spans the full-stack tech chain—from fundamental AI research and wafer fabrication process innovation to chip microarchitecture.
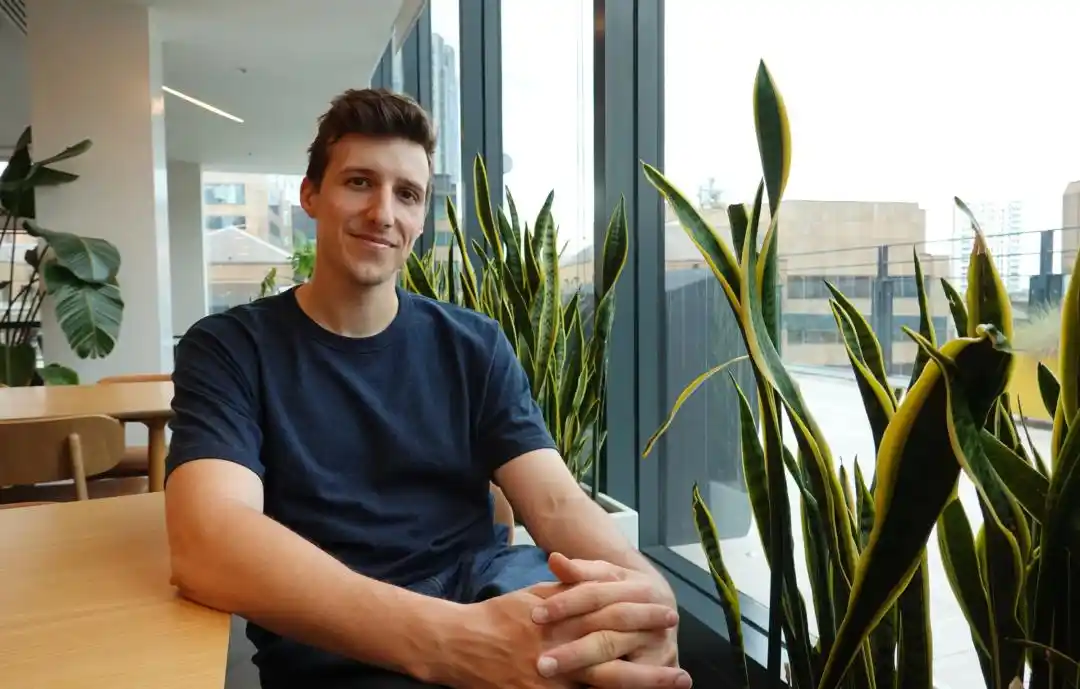
Walter Goodwin, Founder of Fractile, image source: Fractile
Fractile was founded in 2022 by Walter Goodwin, who was only 26 at the time and had just completed his Ph.D. in AI and Robotics from Oxford University.
During his doctoral studies, he focused on leveraging pre-trained vision and language models to develop general-purpose robots capable of adapting to new tasks. Through this work, he gradually concluded that AI would shift from numerous specialized models toward a few large-scale general models—and began contemplating whether existing hardware could sustain the inference demands when these models were repeatedly invoked at scale.
Currently, Fractile’s core executives primarily come from NVIDIA, Graphcore, Imagination, Intel, and Meta.
Specific roles include: Pete Hughes, former Vice President of NVIDIA’s mobile business, overseeing hardware; Alan Alexander, former Chief Processor Architect at Graphcore, and Phil Horsfield, former Chip VP at Graphcore, leading architecture and chip development respectively; Chris Smith, former VP of Software Engineering at Imagination, managing the software team; Dan Rabinovitsj, former VP of Connectivity at Meta, and Stuart Pann, former head of Intel’s Foundry Services (IFS), responsible for system engineering and supply chain management respectively.
Fractile has not yet fully disclosed low-level chip details, but it is confirmed to adopt an in-memory compute architecture. This mechanism eliminates the need to shuttle model parameters back and forth between memory and processor chips, instead embedding computation directly within memory cells.
This technology enables Fractile to overcome the memory bandwidth bottleneck—particularly the limitation of GPU performance—while drastically reducing power consumption.
Other companies employing in-memory computing have mainly deployed their chips in low-power edge devices, whereas Fractile is among the rare few attempting to bring this technology into datacenter-scale workloads.
On the specific memory solution, Fractile made a strategic pivot—from SRAM to DRAM.
Initially, Fractile’s chips were similar to those of Groq or Cerebras, primarily based on SRAM. Because SRAM can be integrated with logic circuits on a single die, it provides extremely high bandwidth between compute units and storage units holding model weights and KV caches, supporting inference speeds of thousands of tokens per second.
However, as model parameter counts grow into the trillions and context lengths expand dramatically, the original architecture faces growing constraints.
Fractile believes that the true transformative potential of high-speed inference lies in supporting long-running Agents. Yet, current high-speed inference chips, despite their high bandwidth, suffer from insufficient memory capacity. In practical deployment, they cannot independently execute long-context attention mechanisms, requiring fallback to GPUs for such computations. Moreover, at datacenter scale, the economic viability of inference ultimately hinges on cost per GB of memory.
To transcend the limitations of SRAM, Fractile has deepened collaboration with memory suppliers and foundries, adopting a 3D-stacked DRAM architecture—directly stacking DRAM on top of the processor’s logic die—to achieve ultra-high bandwidth far exceeding conventional HBM, all from low-cost DRAM. This approach combines the scalability of large-capacity, low-cost DRAM used in GPUs with the speed advantages of chips like Groq or Cerebras.
In chip development, Fractile has also introduced AI-assisted design, utilizing recursive self-improvement (RSI) to compress development cycles.
Traditional place-and-route tools often require days per run. Fractile accelerates early-stage testing using approximate algorithms like fuzzy placement, while prior to launching expensive physical layout experiments, it leverages substantial inference compute power to simulate and refine design proposals—minimizing futile iterations. This allows teams to advance multiple alternatives simultaneously, significantly shortening the gap between identifying model trends and finalizing mass production.
Currently, Fractile has not yet commercially launched a production-ready chip. After transitioning to the DRAM stacking approach, simulations and tests show that its chips can achieve inference speeds 10 to 25 times faster than existing GPUs, while maintaining a one-tenth cost advantage. According to plan, the computing platform will begin mass production ramp-up in late 2027.
The competition in AI inference is no longer just about building a single chip
Training models focus on maximizing computation within limited time, historically prioritizing peak FLOPS. In contrast, inference—especially in Agent scenarios—is more concerned with how quickly individual tasks are completed.
Agents undergo continuous cycles of inference, tool invocation, result acquisition, and further reasoning. Latency from earlier steps accumulates over time. During the decode phase, each generated token requires repeated reads of model weights and continuously expanding KV caches. If data cannot be delivered fast enough, even the most powerful compute units must wait.
Over the past two decades, floating-point compute capacity in chips has increased by approximately 1 million times, while memory bandwidth has grown only about 40 times. If memory bandwidth—historically lagging—could be substantially improved, it would reduce the total compute required to achieve equivalent intelligence levels, enabling exponential gains in overall throughput. As long-context and long-chain tasks become more prevalent, competitive focus is shifting from simply increasing compute capacity to improving memory bandwidth, minimizing data movement, and reducing per-token latency.
Several mainstream approaches are converging on solving the same problem: how to simultaneously achieve sufficient memory capacity and high data read speeds.
NVIDIA, after acquiring Groq’s technology rights, adopted a heterogeneous architecture. The Vera Rubin GPU and HBM handle Prefill, store large-capacity KV caches, and compute Attention, while Groq 3 LPX places model weights in high-speed on-chip SRAM to manage latency-sensitive FFN and MoE computations. Together, the two chips complete a single inference cycle.
Cerebras directly integrates vast amounts of SRAM and compute cores onto wafer-scale chips, leveraging enormous on-chip bandwidth to minimize data movement across chip boundaries. Fractile, building upon in-memory computing, evolved from an early SRAM-based approach to tightly stacking low-cost DRAM with logic dies.
Domestically, companies like Yinsu Computing are also pursuing this space, following a compute-storage co-design path. By combining AI SSDs with near-memory computing chips, they use lower-cost storage resources to alleviate GPU VRAM and system memory pressure, addressing I/O bottlenecks.
The trade-offs behind these strategies remain bandwidth, capacity, cost, and flexibility.
Inference is evolving into a distinct infrastructure industry, with evaluation metrics shifting from peak FLOPS to response speed, cost per inference, energy efficiency, and sustained service capability.
As Agents, long contexts, and diverse model types emerge, a universal GPU system can no longer cover all scenarios. Chips, memory, networks, and software are now being reassembled around different workloads. Large model companies and cloud providers are increasingly involved in chip design, while hardware vendors are extending into racks, networking, and software stacks. The unit of competition is gradually expanding from a single chip to entire inference systems.
This transformation will also generate several new opportunities across the supply chain.
On the chip side, specialized processors optimized for specific inference tasks will continue to emerge, along with new companies focused on memory, advanced packaging, and interconnect technologies. On the infrastructure side, new software will be needed to orchestrate diverse chips, memories, and clusters—boosting utilization and lowering inference costs. On the services side, independent inference clouds and domain-specific compute platforms tailored to particular models and industries may arise.
Looking further ahead, as inference speed improves and costs continue to decline, a range of Agents and real-time AI products currently deemed non-viable due to excessive latency or prohibitive costs will begin to gain commercial feasibility.
Source: Alpha Society
Disclaimer: Contains third-party opinions, does not constitute financial advice


HuggingFace's "AI Duck" Goes Viral, Boosting Chinese Chip Supplier Rockchip
09-02
14 Executives Depart, Horizon Unleashes a Robot Legion
08-11
Nokia Snatches AI Optical Chip Race, Stock Soars 52%
08-07
AI stocks down 40%-60%, yet NVIDIA's valuation is at a 10-year low
08-06
HBM Bottleneck Migration, NVIDIA Also Aims to Downgrade
08-06
AI Servers Fuel Demand for Minor Metals: Prices Surge Over 70% in Half a Year
08-06
AI is not a search bar—it's a supercomputer costing just a few dozen dollars
08-05


